Level Up Your Automation: Best Practices for Reliable, Repeatable Testing in Distributed Test Systems
Overview
Modern validation labs operate as distributed test systems and automated test environments, where many testers, software stacks, and hardware assets must remain synchronized. Without structured control, configuration drift can introduce inconsistent results, retests, and operational risk. The following best practices help validation teams maintain reliable, repeatable testing across distributed systems.
Reliable validation in distributed test systems requires more than monitoring individual stations. It requires controlling the entire test environment through structured deployment, system states, governance, and operational telemetry.
This white paper covers the following key points:
- Distributed test systems require structured environment management. Consistent software and configuration across testers is critical for repeatable results.
- Configuration drift is a leading cause of unreliable tests. Small changes to drivers, scripts, or configuration files can cause systems to diverge.
- Centralized deployment keeps environments consistent. Packaging and distributing complete runtime environments prevent station-to-station variation.
- Golden states define validated system configurations. Approved baselines allow engineers to detect drift and replicate working environments.
- Workspaces and role-based access control (RBAC) improve governance. Segmentation and controlled permissions prevent unintended changes across distributed systems.
- Telemetry monitoring helps prevent avoidable failures. System health monitoring and alarms help identify issues before they invalidate tests.
- Calibration tracking ensures hardware validity. Linking asset calibration status to execution improves reliability and traceability.
- Traceability connects software, assets, and test results. Deployment history and system state records support debugging and audits.
Contents
- What Is Test Environment Management?
- The Cost of Invisible Differences
- The Nature of Drift in Validation (and How It Multiplies)
- Centralized Deployment: Package and Promote Everything That Changes
- Versioning, Notes, and SBOM Mindset
- Golden States: Define, Compare, and Enforce “What Good Looks Like”
- Workspaces and Roles: Structure for Real Organizations
- Runtime Health and Readiness Gates: Prevent the Preventable
- Calibration and Asset Readiness: Tie Hardware Validity to Software Repeatability
- Controlled Update Cadence: Security without Surprises
- KPIs (Table Only)
- Operational Best Practices for Stable Test Environments
- Conclusion: Make Repeatability Predictable
- Next Steps
What Is Test Environment Management?
Test environment management is the practice of controlling the software, hardware, and configuration dependencies required to run automated tests reliably. In distributed test systems, this includes managing application versions, drivers, runtime environments, configuration files, hardware assets, and deployment processes across many test stations. Effective test environment management ensures that every tester executes under the same validated conditions, preventing configuration drift and enabling repeatable results.
The Cost of Invisible Differences
In modern distributed test systems, even small differences between stations can quickly create problems. On Monday, Station B’s rise time was 3 percent slower than Station A’s. On Tuesday, an overnight Windows update appeared but only on half the machines. On Wednesday, a Python utility silently changed because someone “updated it on their box.” By Friday, a week’s worth of results was under dispute because no one could prove what software, drivers, and configurations were in use when the failures occurred.
Every validation engineer has lived some version of that story, not because teams are careless, but because validation moves fast: prototypes arrive mid‑cycle, requirements shift, test coverage expands, and cross‑functional teams touch the same hardware. The job is to learn quickly from experiments, not to babysit configurations. Yet invisible differences, or configuration drift, are the single biggest driver of retests, late-night debug sessions, and audit anxiety.
Configuration drift occurs when systems that are intended to be identical gradually diverge due to untracked software updates, configuration changes, or infrastructure differences.
Whether you manage 4 stations or 400, NI SystemLink™ software helps validation organizations turn configuration drift from an invisible source of risk into an engineered, enforceable discipline. It provides a structured way to package and distribute everything that changes, codify “what good looks like” with centralized deployment and system states, segment complex labs using workspaces and roles, prevent avoidable failures with runtime health and readiness gates, and link asset calibration to execution so software repeatability and hardware validity move in lockstep.
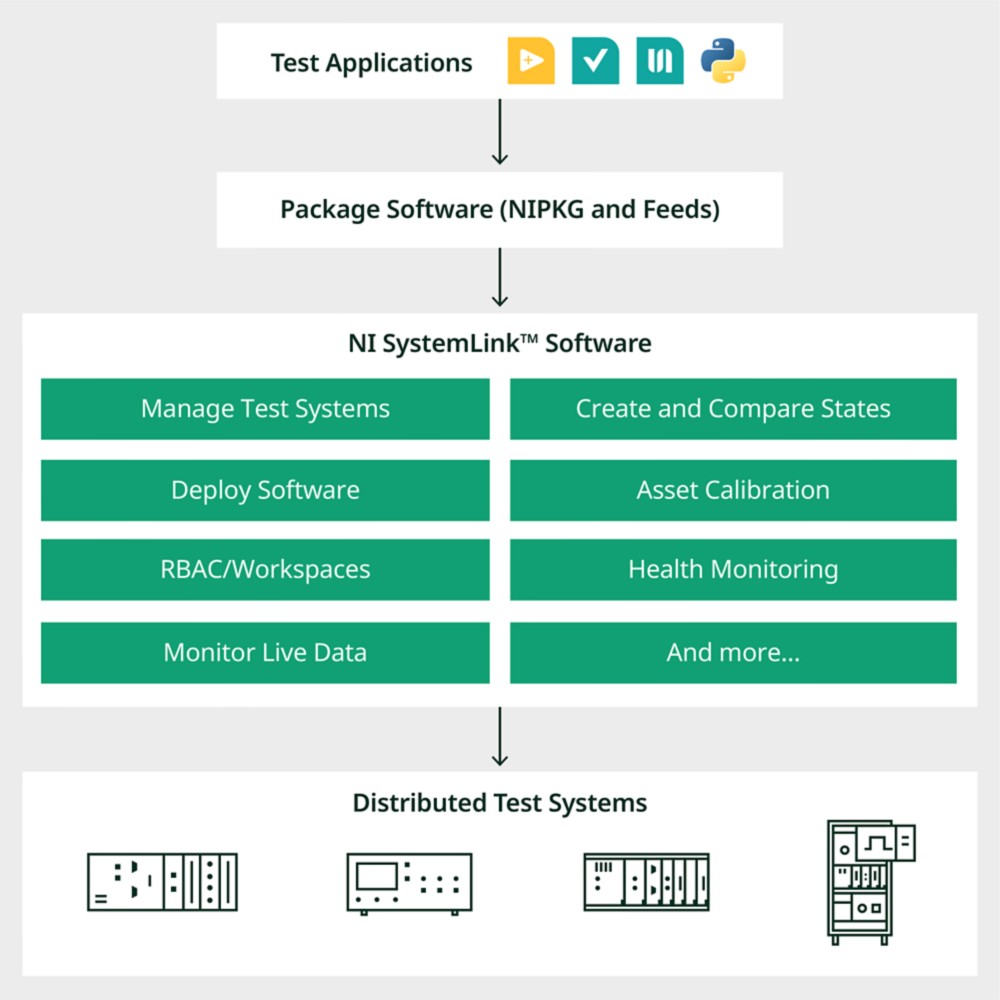
Figure 1. SystemLink Architecture for Software Deployment and Management across Distributed Test Systems
The goal is simple: make repeatability predictable so validation teams can focus on engineering, not firefighting. SystemLink gives the lab the infrastructure to move fast without losing control of configurations, assets, and test data.
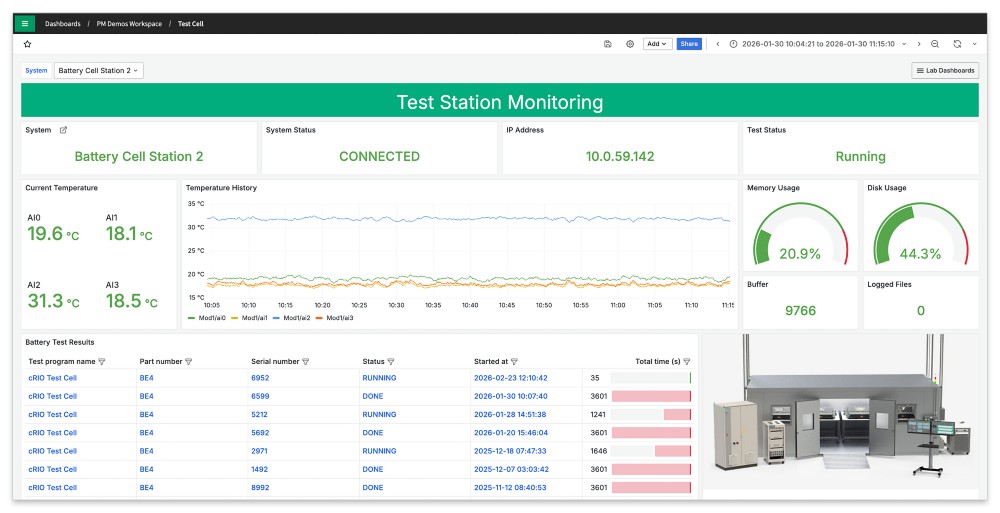
Figure 2. Centralized Test Station Monitoring Dashboard in SystemLink
The Nature of Drift in Validation (and How It Multiplies)
Drift accumulates through reasonable, everyday actions: a driver is hotfixed on one station to unblock a test; an NI TestStand process model is modified for a one‑off product exception; an NI LabVIEW Runtime patch lands on three machines, but not the rest; an NI FlexLogger™ software configuration is copied manually “just for now”; security updates apply on a subset of computers during a long run; and a Python script on a shared drive is overwritten with a “newer” variant.
Each change is small, local, and often untracked. Together, they create divergence, and divergence erodes repeatability. The symptoms are familiar: failures that reproduce on one station but not another; subtle measurement deltas between “identical” testers; long overnights wasted because a logging service quietly stopped; and audits turned into archaeology digs.
The pattern behind the pain: when engineers can’t answer the following four questions right away, repeatability depends on memory, not control:
- What’s running where? Which application version is installed on each station?
- What’s underneath? Which runtime, driver stack, models, and utilities are installed?
- Who changed what, and when? What changed between last week’s pass and this week’s?
- Is the station truly ready? Are software and hardware assets (calibration) verified?
Consider a battery validation lab running durability testing across dozens of automated test stations. Each system executes LabVIEW data acquisition, TestStand sequences, and supporting Python utilities. Over time, small changes, such as a driver update, a modified configuration file, or a patched runtime, cause systems to diverge. When failures appear on one station but not another, engineers spend hours investigating differences instead of analyzing results. Managing deployment, configuration states, and operational health centrally allows the team to maintain consistent testing across the entire lab.
SystemLink addresses these questions directly. It packages the entire runtime environment, distributes it through managed feeds, codifies golden states that systems must match, segments the lab with workspaces and role-based access control (RBAC), monitors runtime health, enforces readiness gates, and ties in calibration so stations are actually ready.
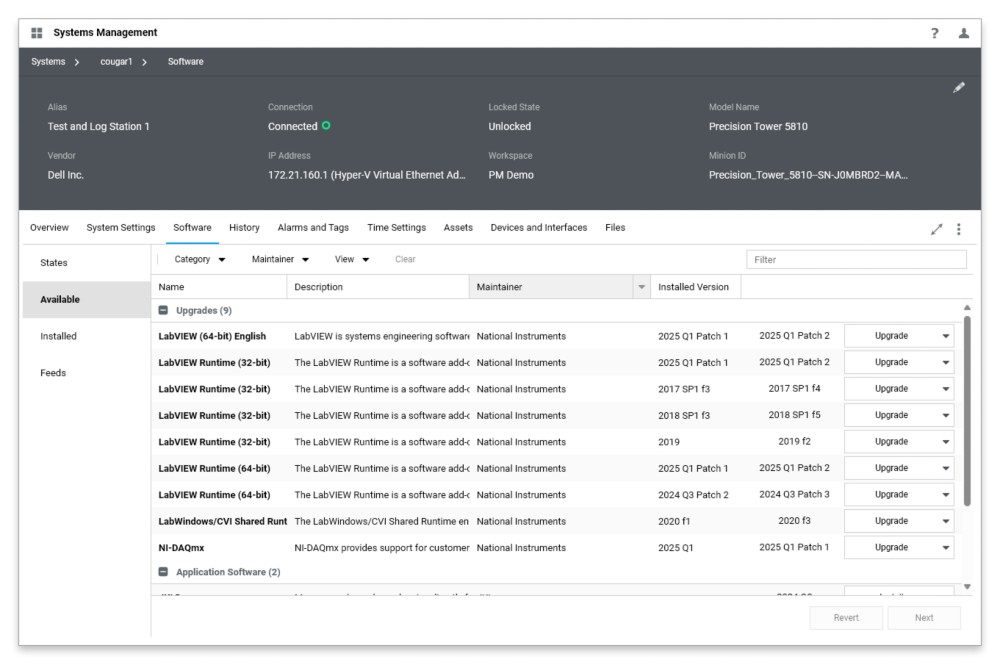
Figure 3. SystemLink Systems Management Interface Showing Available Package Upgrades
Addressing drift requires more than visibility. It requires control over how test environments are built and maintained. The first operational step is ensuring that every system receives software updates in a controlled and repeatable way. Instead of manually installing components or copying files between testers, validation teams need a structured deployment process that packages the entire runtime environment and distributes it consistently across the lab. Centralized deployment provides that foundation.
Centralized Deployment: Package and Promote Everything That Changes
Repeatability starts with controlling what goes on every tester—and making those changes intentional. In validation, “the application” is never just an EXE. It’s the entire runtime environment: LabVIEW applications and runtimes; TestStand sequences, models, and custom steps; FlexLogger and NI InstrumentStudio™ software configurations; drivers and hardware abstraction layers; Python/C/C++ utilities and supporting scripts; limit files, INIs, hardware maps, and configuration JSON; and OS‑level dependencies needed by your test stack.
In distributed test systems used for validation and test, manually installing software or copying files from station to station quickly creates divergence between machines. Over time, each tester develops its own configuration “personality,” making it difficult to ensure tests are running under identical conditions. SystemLink replaces this ad-hoc approach with managed NIPKG package feeds so software environments remain versioned, centrally distributed, and traceable across the entire fleet of test systems.
1. Promote Changes through Feeds: Development → Validation → Production
A straightforward promotion flow from development to production gives validation teams control without friction:
- Development for integration builds and internal testing
- Validation for stable, cross‑team approved releases used in formal campaigns
- Production for frozen versions used for long‑running or regulated tests.
Governance patterns include restricting write/publish rights on Validation and Production feeds, requiring promotion rather than direct uploads into Production, and recording release notes, version numbers, and dependencies with each package.
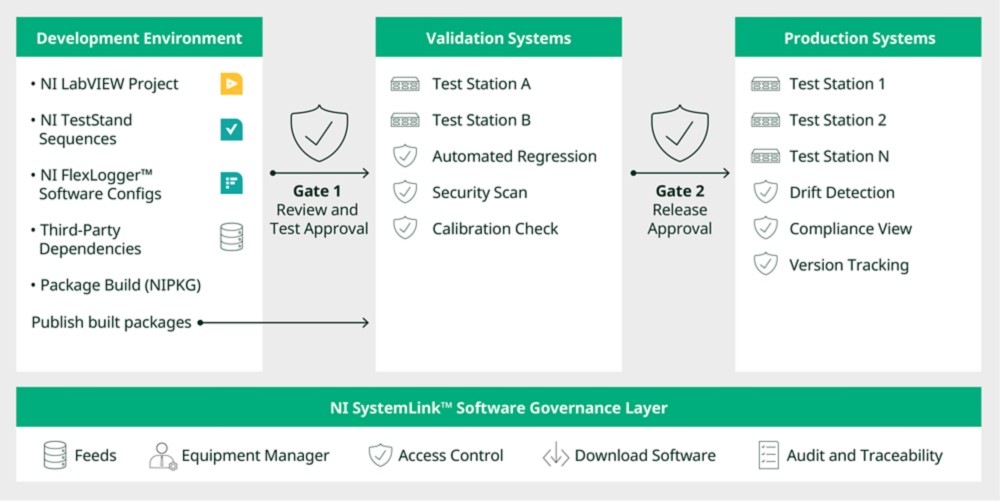
Figure 4. Controlled Deployment Lifecycle for Distributed Test Systems
2. Preparing Software for Deployment (Packaging Best Practices)
Before environments can be deployed and governed through SystemLink, the software that defines those environments must be packaged in a consistent and versioned form. In validation labs, packaging is therefore a critical prerequisite to centralized deployment.
Test applications depend on far more than a compiled executable. A typical runtime environment may include LabVIEW applications and libraries, TestStand sequences and process models, FlexLogger or InstrumentStudio configurations, Python or C/C++ utilities, limit files, configuration files, and hardware mappings. Packaging these components together ensures that the full execution environment can be deployed consistently across distributed test systems.
Validation teams typically use one of the following approaches to create deployment packages.
- Build and Package from LabVIEW—If your application is primarily LabVIEW, generate your executable and produce a NIPKG from the project’s build outputs. This process is simple and works well when the environment is relatively application‑centric.
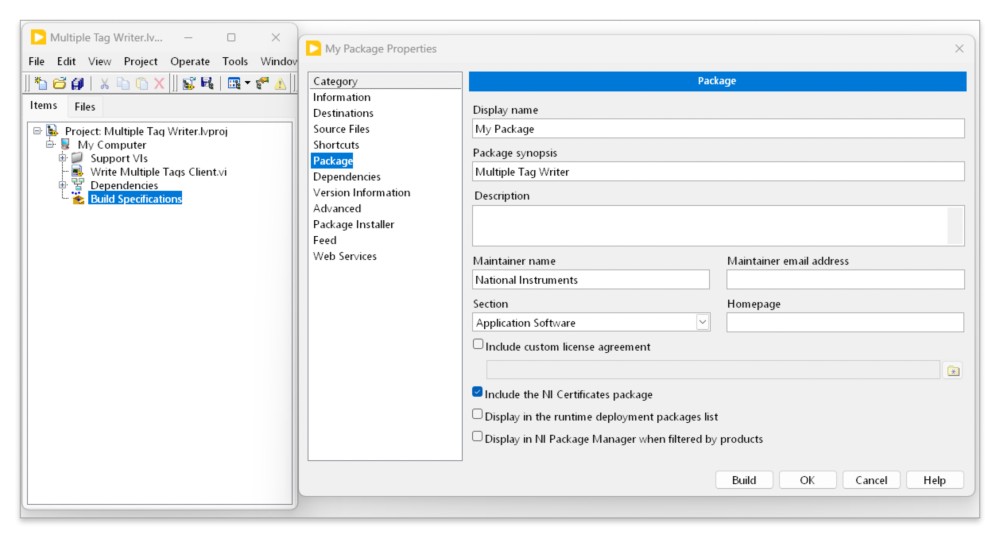
Figure 5. Building a Deployment Package from a LabVIEW Project
Use NI Package Builder for Full Runtime Environments—For validation labs, NI Package Builder is often the better choice. It lets you assemble the full runtime: include LabVIEW EXEs and libraries; add TestStand sequences/models and custom steps; bundle FlexLogger/InstrumentStudio configurations; package limit files, hardware maps, and INIs; set install directories and add pre/post‑install scripts; declare driver and runtime dependencies explicitly; and stamp semantic versions with release notes.
For step-by-step instructions on how to build a package, visit Creating a New Package.
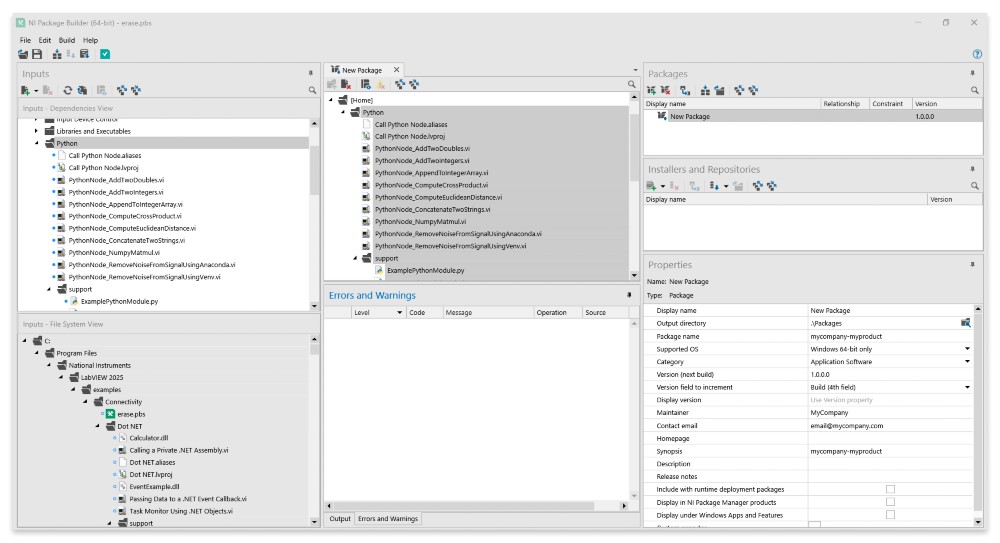
Figure 6. Creating a Deployment Package with NI Package Builder
- Package Third‑Party Tools—Wrap Python utilities, C/C++ binaries, command‑line tools, or vendor drivers into NIPKGs with pinned versions. No more “works on my station” surprises.
- Connected versus Air‑Gapped Labs—Connected labs can resolve dependencies via approved feeds; air‑gapped labs mirror approved drivers internally, hosting everything on SystemLink so deployments happen entirely on the internal network.
The bottom line is to avoid manually copying FlexLogger configuration files or LabVIEW executables between stations. Instead, as a best practice, create a package that includes the required files, apply clear naming and versioning, and deploy it consistently across your test systems.
Versioning, Notes, and SBOM Mindset
A common best practice in validation environments is to apply semantic versioning (Major.Minor.Patch) to every test‑program release. This labeling helps teams communicate the intent of each change—whether it introduces new functionality, modifies behavior, or applies a small fix. The version should be applied at the point where your application or sequence bundle is packaged, such as in a LabVIEW package build or any other packaging tool your team uses.
Your release metadata typically focuses on the artifacts you own:
- Your validation application
- TestStand models and sequence bundles
- FlexLogger or InstrumentStudio configurations
- Supporting Python/C/C++ utilities
- Configuration files, limit files, and hardware maps
A manifest might look like the following example:
"release": "Validation-2026.02.1",
"program-packages": [
{ "name": "VAL-App", "version": "2.3.0" },
{ "name": "TestStand-Model", "version": "1.5.2" },
{ "name": "FlexLogger-Config-Powertrain", "version": "4.1.0" },
{ "name": "Python-Utilities", "version": "1.8.7" }],
"notes": "Adds transient capture fix; updates RTD scaling; Q1 improvements."}
While you maintain semantic versioning for your own software and configurations, there are also tools—such as states in SystemLink—where you can add drivers, dependencies, and runtime components on a reference machine. You do not need to manually list NI drivers or OS‑level components. They’re captured automatically as part of the state definition.
In practice:
- Version program artifacts.
- Add drivers to a state so the system captures the full dependency stack for traceability.
This process creates a complete picture of the execution environment without requiring you to manually maintain an exhaustive list of drivers.
Golden States: Define, Compare, and Enforce “What Good Looks Like”
Deployment gives you consistency on Day 1. Golden states keep that consistency on Day 100.
A golden state is a named, versioned snapshot of the approved software configuration for a tester or a group of testers. It specifies exactly which packages and versions must be present for the system to be considered compliant.
Golden states define the approved configuration baseline for a tester or group of testers.
After they are defined, they allow teams to detect drift, verify compliance, and replicate validated environments across distributed systems.
Two Ways to Create Golden States
Validation teams typically establish golden states in one of two ways:
Approach 1—Curate the State from Known Packages
Define the baseline by selecting the specific application packages, configuration artifacts, models, and utilities that make up your validated runtime.
This approach works well when your environment is already structured around clear release processes and package promotion through feeds. This method is ideal for the following scenarios:
- Green‑field teams formalizing their release pipeline
- Mature validation groups with multi‑team governance
- Product lines that need clean separation and tailored baselines
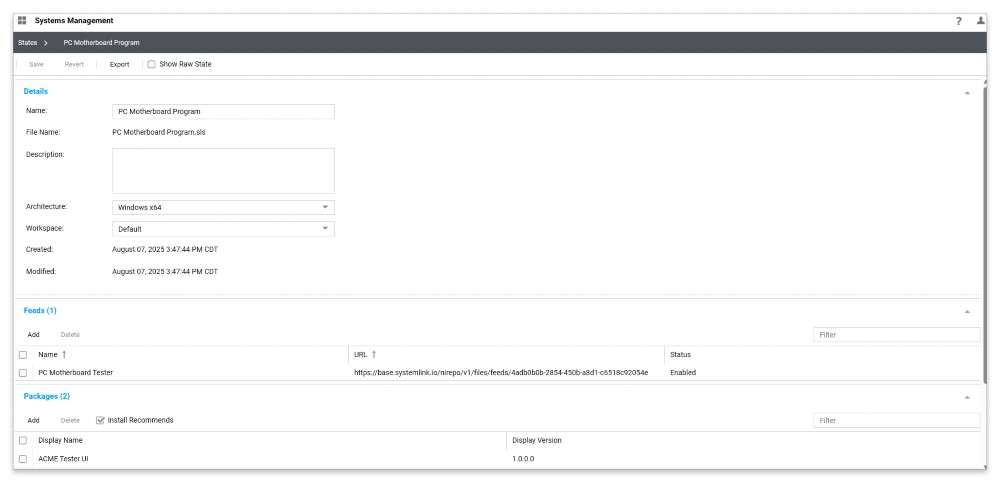
Figure 7. Creating a System State from Approved Software Packages in SystemLink
Approach 2—Capture a Reference System
Sometimes the most reliable starting point is simply: “freeze whatever is working today.”
In this approach, you configure a reference tester, validate it, and capture its installed inventory as a golden state. SystemLink records all NI-packaged software, registered drivers, and depends. This method is especially valuable for the following scenarios:
- Labs formalizing control for the first time
- Programs emerging from a long debug cycle
- Environments where many contributors have touched a system over time
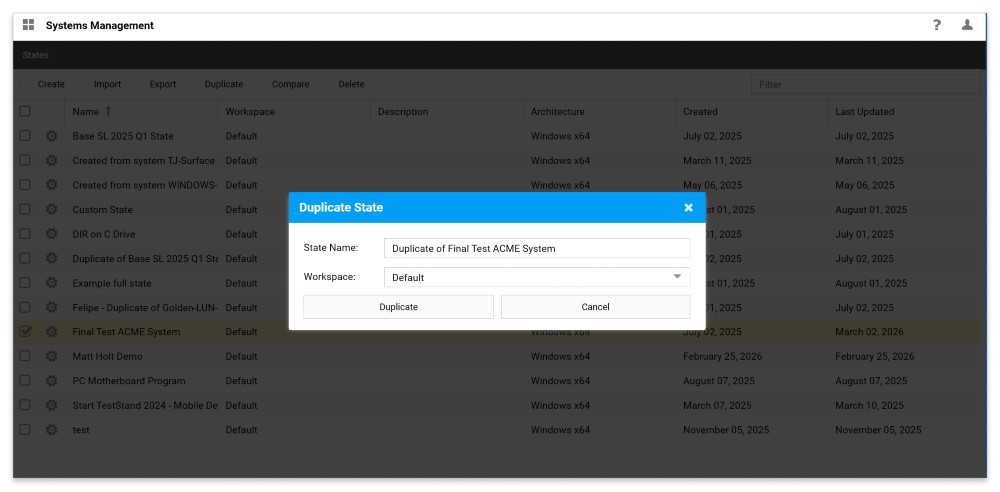
Figure 8. Duplicating a System State to Replicate a Validated Test Environment
Compare and Understand Drift (Before It Costs You)
After golden states exist, SystemLink makes drift visible. You can make the following comparisons:
- A system to its assigned state
- Two systems to each other
- Two state versions (ideal for release reviews)
Differences surface immediately: missing packages, extra packages, version mismatches, and dependency changes. This comparison transforms the act of debugging from guesswork into evidence‑based analysis.
A validation engineer no longer has to wonder why a failure reproduces on one station and not another because the exact differences are shown in a structured diff.
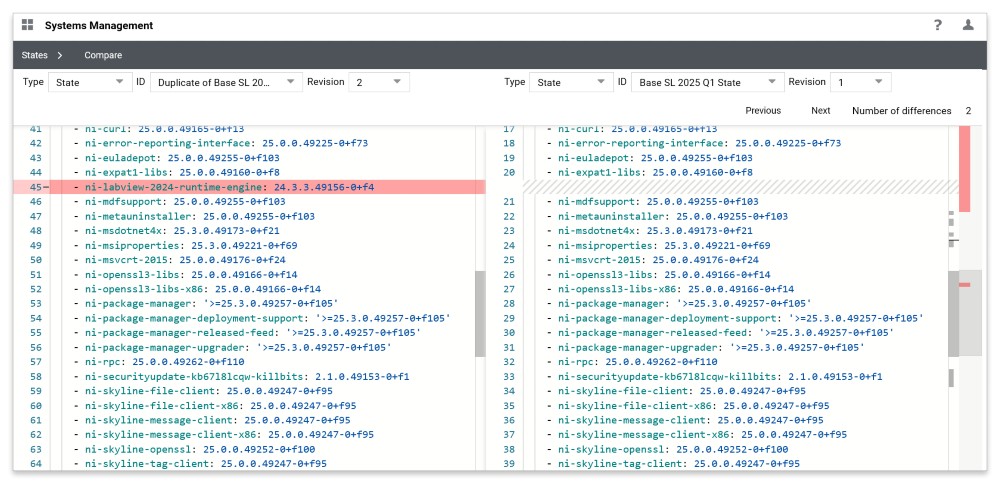
Figure 9. Comparing System States to Identify Configuration Drift
Workspaces and Roles: Structure for Real Organizations
A best practice in any validation lab is controlling who can deploy what. Data is currency, and mis‑scoped access leads to mis‑scoped deployments. Since validation spans many environments, not just one—Product Line A versus Product Line B, reliability versus performance, early integration versus regulatory testing—structured separation matters. Workspaces and role‑based access enforce that separation without isolating teams.
Workspaces: Logical Separation with Shared Infrastructure
SystemLink workspaces partition the lab by program, site, release cadence, or risk profile. For example, you can differentiate Product Line A versus Product Line B; validation versus reliability versus production QA; regional labs; or early prototype versus late qualification. Each workspace scopes nodes, feeds, golden states, dashboards, alarms, and permissions relevant to that environment.
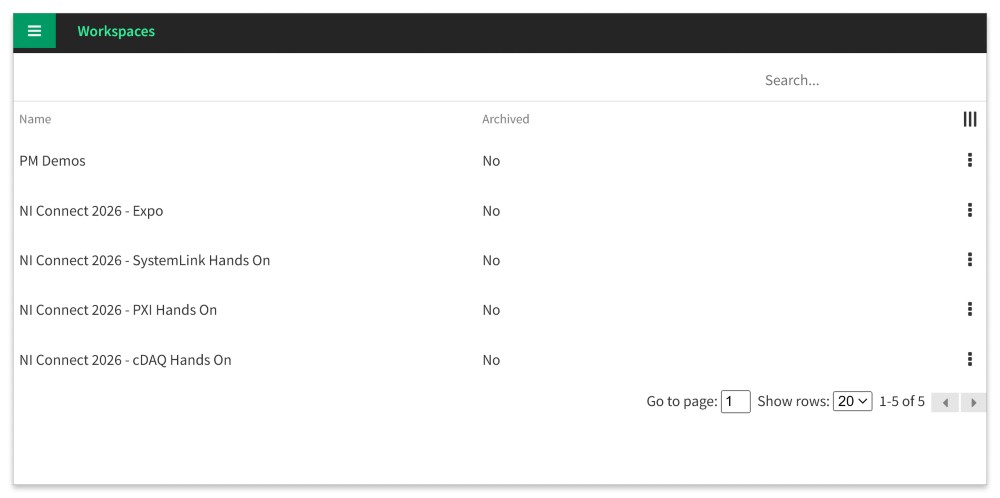
Figure 10. Organizing Test Environments with SystemLink Workspaces
RBAC: Authority That Matches Responsibility
In test or validation organizations, responsibilities typically fall into a few common roles. Administrators manage global settings, package feeds, and state frameworks. Deployment engineers publish and promote software packages and manage rollouts across test systems. Maintenance engineers respond to alarms, restart services, and ensure stations remain operational. Operators execute tests and monitor system status with read-only access.
SystemLink implements these responsibilities through role-based access control (RBAC). Roles can be scoped by workspace so that engineers responsible for one program or product line cannot modify the baseline of another. This separation reduces operational risk while improving traceability and auditability.
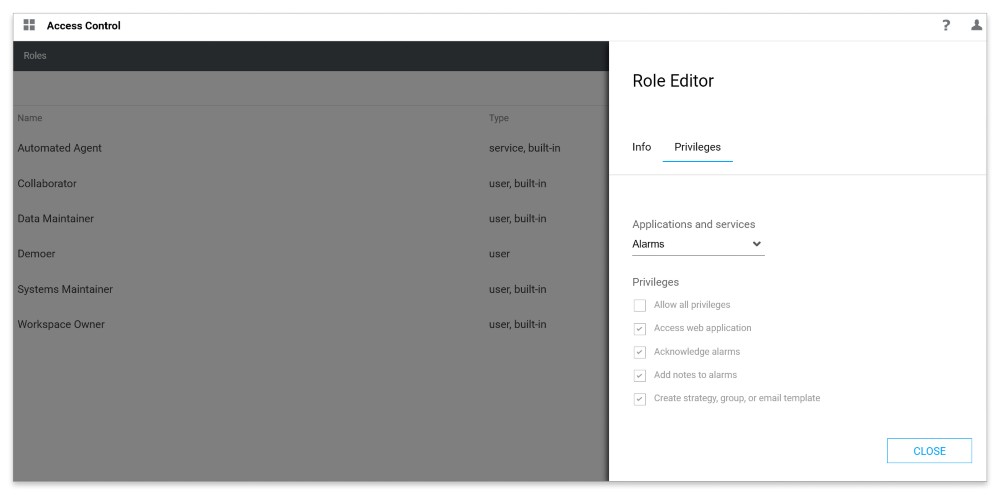
Figure 11. Role-Based Access Control Configuration in SystemLink
Runtime Health and Readiness Gates: Prevent the Preventable
Even perfectly deployed systems can degrade. Long validation runs are sensitive to issues like low disk, runaway memory, downed services, and unstable networks. SystemLink collects telemetry and turns it into alarms so that you can fix issues before they invalidate runs.
Telemetry to Alarms
Monitor CPU and memory trends, available disk space and write throughput, network connectivity for publishing/logging, service uptime (data, execution, communications), and device/driver health where supported. Define alarm rules that reflect expected workload behavior—tight enough to catch real issues, loose enough to avoid fatigue.
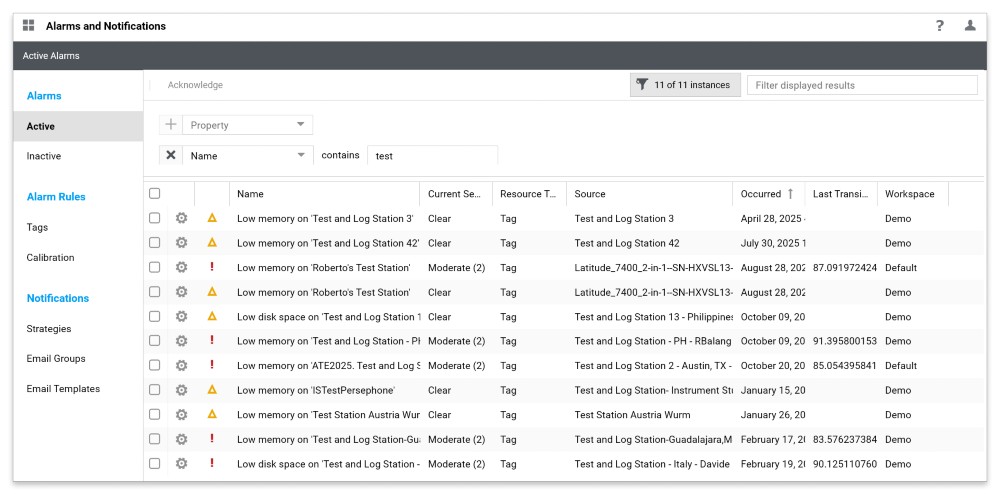
Figure 12. Monitoring Test System Health with SystemLink Alarm Notifications
Readiness Gates: Don’t Start When You’re Not Ready
The most powerful operational pattern for validation teams is readiness gating: block new tests from starting when a system is in an alarm state or when required assets are invalid. If disk space is below the safe threshold, don’t start. If a logging service is down, don’t start. If a required instrument is out of calibration, don’t start. Integrate gates with your frameworks using SystemLink APIs.
The cheapest failure is the one you never start.
Calibration and Asset Readiness: Tie Hardware Validity to Software Repeatability
A station isn’t ready just because the software is compliant. Validation depends on calibrated, known‑good, traceable hardware: instruments, fixtures, sensors, data acquisition (DAQ) modules, switch matrices, custom test heads, and references. SystemLink tracks asset identity, calibration expirations and status, self‑test/self‑cal results where supported, and station–asset bindings.
Visibility and Control
Use asset data in readiness gates and alerts: proactively notify owners at 30, 14, and 7 days before expiration; block execution when required assets are invalid; and record calibration state alongside test results.
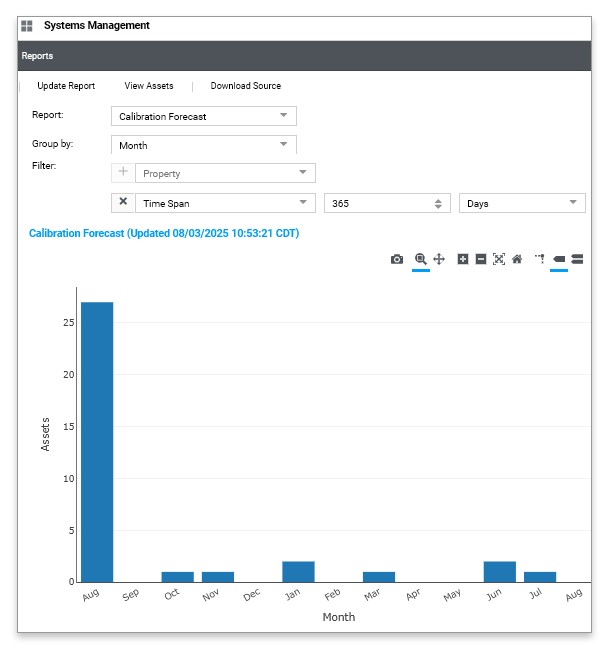
Figure 13. Calibration Forecast Report for Test Assets in SystemLink
Traceability Chain
Link each test to deployed software versions (packages and golden state version), deployment history (who changed what and when), and asset identity and calibration status at run time. This traceability is invaluable for internal quality, customer qualification, and regulatory audits across industries from aerospace and medical devices to automotive, energy, and consumer electronics.
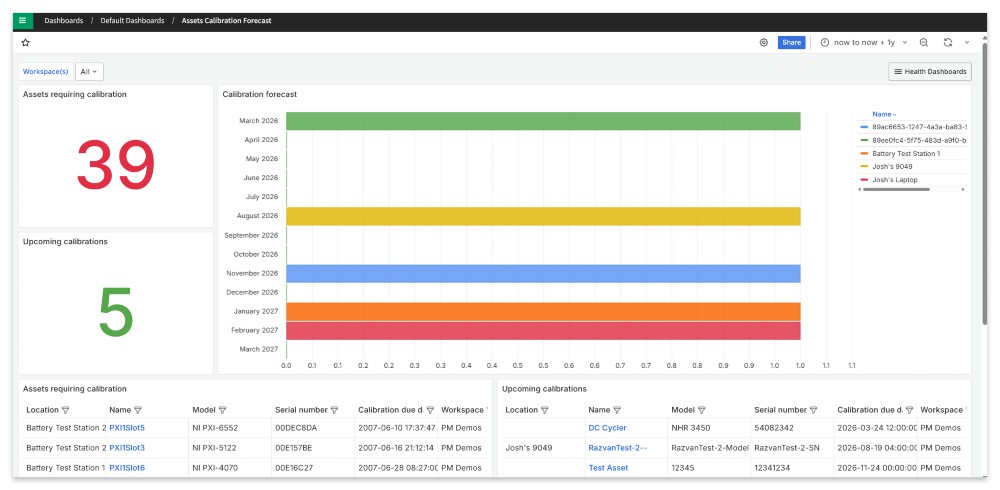
Figure 14. Monitoring Asset Calibration Status and Forecasts in SystemLink
Controlled Update Cadence: Security without Surprises
Validation teams must reconcile stability (don’t change mid‑campaign) with security (apply critical patches). SystemLink enables planned, staged updates so you can move fast without breaking trust in results.
- Rollout Rings—Using SystemLink, you can deploy in waves: first, Pilot, a representative subset of systems; then, Limited, which includes more systems in the same workspace; and finally, Full, which covers the entire validation fleet for that program or site. Each ring increases confidence while bounding risk.
- Scheduling and Windows—Schedule deployments during maintenance windows, between campaigns, or outside long‑run cycles. Avoid surprise changes that collide with environmental or endurance testing.
- Traceability and Rollback—SystemLink logs who deployed what to which systems and when. Keep prior versions accessible so you can roll back by reapplying the last known good package set. Using SystemLink, you can include concise release notes so validation owners can approve changes with context.
KPIs (Table Only)
To understand whether these practices are improving stability and repeatability in the lab, teams can track a small set of operational indicators. The following KPIs offer a practical way to measure configuration control, deployment quality, and overall test readiness.
Operational Best Practices for Stable Test Environments
- Version everything—Use semantic versioning for test applications, configuration files, and utilities to make changes traceable across distributed test systems.
- Package configurations alongside applications—Deploy configurations, limit files, and hardware mappings as versioned artifacts rather than copying them manually between stations.
- Align environment ownership with infrastructure boundaries—Separate programs or product lines using clear governance structures such as workspaces and controlled permissions.
- Monitor infrastructure health continuously—Disk space, memory, services, and connectivity can affect long-running validation tests and should be monitored proactively.
Conclusion: Make Repeatability Predictable
Validation lives at the intersection of complexity and urgency. Prototypes evolve, requirements shift, and schedules tighten. In that environment, configuration drift is inevitable—unless the lab has infrastructure that makes consistency the default.
SystemLink provides that infrastructure for validation organizations. It can package and promote everything that changes; define, compare, and enforce golden states; segment the lab with workspaces and role-based access control; monitor runtime health and respond to alarms; gate execution on readiness conditions such as compliance, active alarms, or calibration status; and trace changes across deployments, system states, and assets.
Whether a team manages 4 stations or 400 hundred, these practices scale because the unit of control is the package and the state, not the person at the keyboard. When drift becomes visible and readiness becomes intentional, validation moves faster, results become clearer, and audits become routine.
Make repeatability predictable. Take control of the environment so your engineers can focus on what matters most: the product.
| Metric | Description | Target/Trend |
|---|---|---|
| Configuration Drift Rate | Percentage of systems out of compliance | Decreasing |
| Time to Remediate Drift | Detection-to-compliance time | Hours |
| Deployment Success Rate | Successful updates per wave | High 90s% |
| Blocked Starts (Readiness Gates) | Prevented runs due to alarms or calibration | Low but non‑zero |
| Retest Rate Due to Environment Issues | Retests linked to configuration errors | Decreasing |
| Audit Readiness | Ability to produce required reports | Pass/Fail |